FINAL_EVIDENCE_VERIFIED · generated 2026-10-12T04:41:06.704740+00:00
Strata on a 16GB RTX 5070 Ti
Sonny’s Labs · v0.1.43 · 64GB installed RAM · IQ2_XS versus IQ3_XXS
This local experiment tests whether a large MoE deployment can serve useful coding and agent workloads with limited VRAM and RAM, while moving compilation and downloads out of runtime. The original practical/coding index and long-context reliability are reported separately. Any incomplete results remain explicitly pending in draft builds.
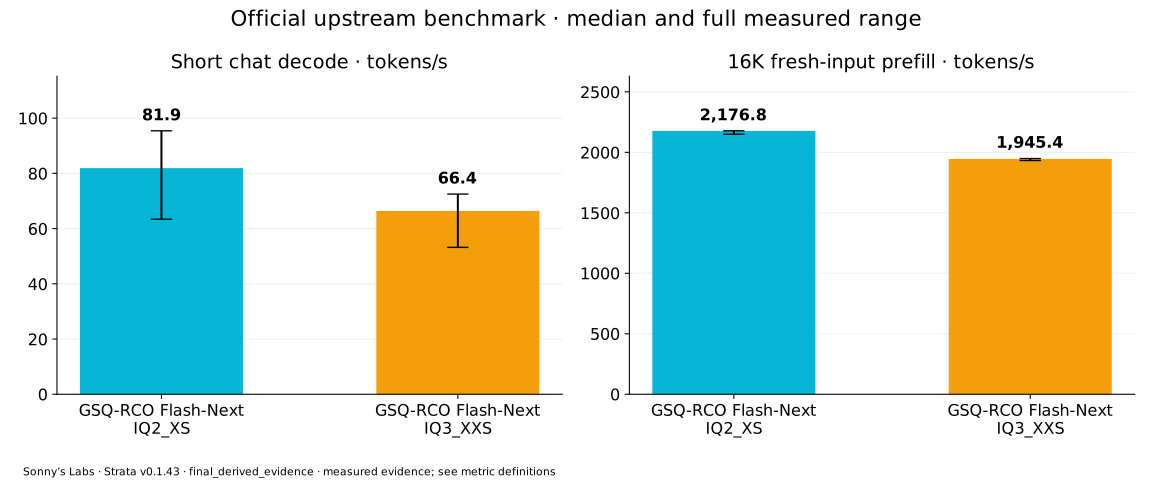
Official upstream measurements
| Quant / context | Chat decode tok/s | Chat TTFT s | 4K prefill tok/s | 16K prefill tok/s |
|---|---|---|---|---|
| IQ2_XS / 32,768 | 81.9 | 0.389 | 1,459.5 | 2,176.8 |
| IQ3_XXS / 32,768 | 66.4 | 0.488 | 1,210.0 | 1,945.4 |
Three measured repetitions; upstream warmup discarded, thinking off. Engine prefill/decode timings and streaming client TTFT retain the original methodology. Full measured ranges. Original upstream files and submission instructions: IQ2_XS · IQ3_XXS (links appear when packages exist).
| Quant / 64K allocation | 32K prefill tok/s | 32K TTFT s | Agent prefix reuse % | Agent reread tokens/session | Agent follow-up decode tok/s | Two-client combined tok/s | Two-client TTFT p95 s | Client errors |
|---|---|---|---|---|---|---|---|---|
| IQ2_XS | 2,183.4 | 14.711 | 68.62 | 74 | 86.5 | 65.93 | 2.988 | 0 |
| IQ3_XXS | 1,939.8 | 16.560 | 68.65 | 74 | 72.7 | 48.71 | 3.876 | 0 |
Upstream actual 32K input is reported in the raw files. The agent session contains an initial turn plus five follow-ups. Prefix reuse is distinct from hot-expert cache occupancy. Two-client statistics include FIFO waiting on one serial slot; the standard and optional results remain separate.
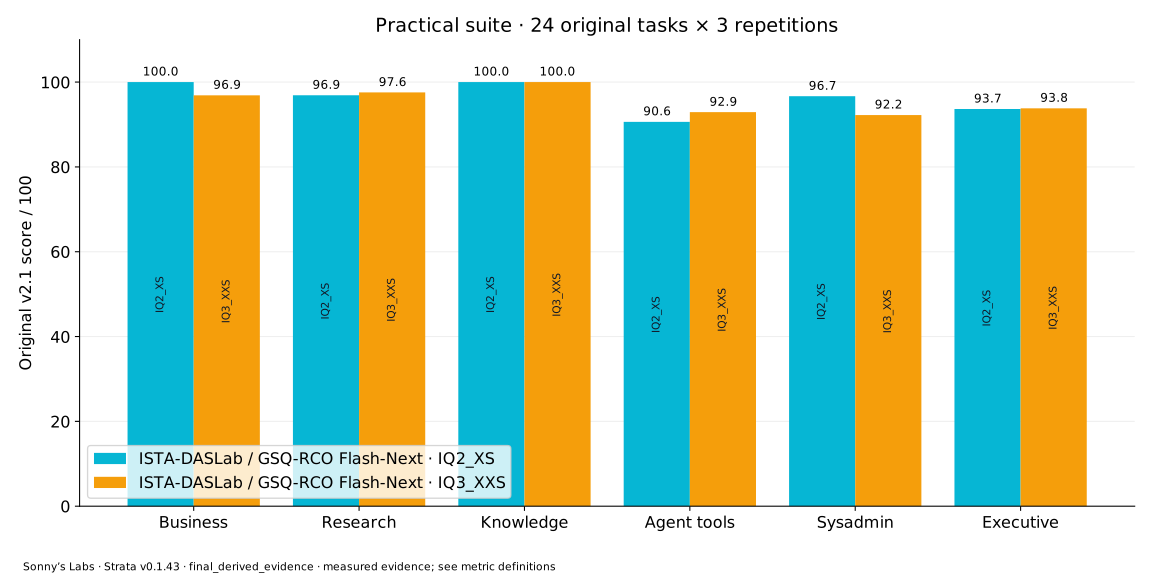
Original Sonny’s Labs v2.1 scoring
| Quant | Practical responses | Empty practical | Length finishes | HumanEval+ evaluated | HumanEval+ % | Balanced score / 100 |
|---|---|---|---|---|---|---|
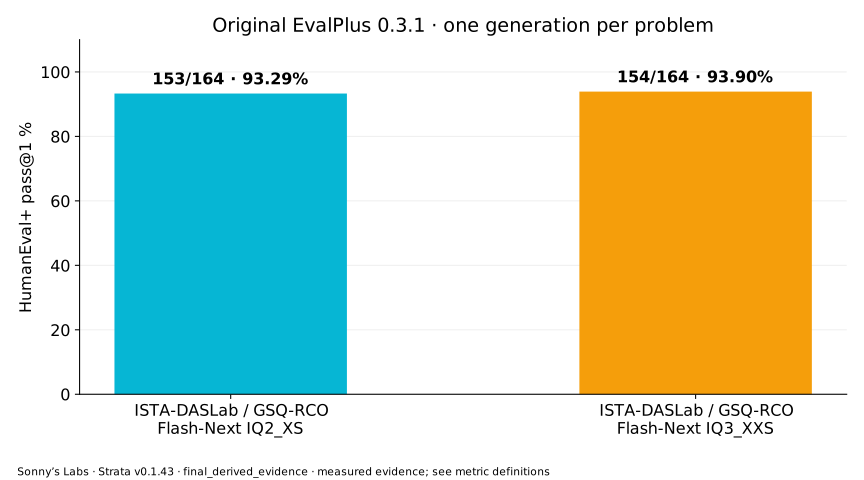
| IQ2_XS | 72 | 0 | 2 | 164 | 93.29 | 96.50 |
| IQ3_XXS | 72 | 0 | 3 | 164 | 93.90 | 96.21 |
Unchanged 24 practical tasks, three repetitions, 2,048 output cap; all 164 original HumanEval+ problems with EvalPlus 0.3.1 in a network-isolated scorer. The retained weights are business 20%, research 20%, knowledge 20%, agent tools 15%, sysadmin 5%, HumanEval+ 10%, executive content 10%. The scorer’s rebuilt transitive dependencies are inventoried, rather than claimed byte-identical to history.
| Original role weighting | Highest score /100 | Quantization(s) |
|---|---|---|
| C-Suite / Analyst | 98.12 | IQ2_XS |
| Researcher / Scout | 97.04 | IQ3_XXS |
| Hermes Coordinator | 95.77 | IQ3_XXS |
| Librarian / Knowledge | 96.89 | IQ3_XXS |
| Forge / Coder | 94.42 | IQ2_XS |
Role maxima use the original practical/coding weights and exclude long-context quality. Separate dossier reliability and speed qualification are available in the structured evidence.
| Quant | Workload | Responses | Median total s | Max total s | Median engine decode tok/s | Median uncached prefill tok/s | Draft acceptance % | Prefix reuse % |
|---|---|---|---|---|---|---|---|---|
| IQ2_XS | practical | 72 | 5.58 | 31.53 | 95.1 | 227.2 | 81.35 | 0.00 |
| IQ2_XS | humaneval | 164 | 5.07 | 10.92 | 93.1 | 258.4 | 78.37 | 0.00 |
| IQ3_XXS | practical | 72 | 8.16 | 38.00 | 74.5 | 183.2 | 79.58 | 0.00 |
| IQ3_XXS | humaneval | 164 | 6.83 | 15.13 | 73.1 | 209.6 | 78.75 | 0.00 |
These original clients are nonstreaming: total request latency is measured, while client TTFT is unavailable for these rows. Engine counters provide prefill/decode timing. Draft acceptance combines the exposed speculation counters and must not be called an isolated MTP-only acceptance rate. Short-prompt rates include fixed overhead and should not be compared directly with long-input prefill.
Compatibility and retained failures
| Feature | Measured behavior / limitation |
|---|---|
| Discovery / completions / streaming | Diagnostics retained for each quant; actual configured model name used by the minimal adapter. |
| Tool calls | Forced function call and client-supplied result roundtrip tested. Server-side MCP execution disabled; broader task performance uses the unchanged agent-tools rubric. |
| JSON outputs | Valid JSON examples returned. Optional strict-schema validator is absent, so strict schema enforcement is unsupported in this image. |
| Reasoning / token accounting | Separate reasoning_content and API usage/timing fields retained; original Sonny reasoning budget 512, upstream official thinking off. |
| Context / timeouts / concurrency | No server /tokenize endpoint: unmodified upstream Tokenizer counts dossier text. API context guards preserved. Original client timeout 1,800 s; one serial slot. |
| Finish reasons / empty finals | stop/length preserved; truncations and empty answers remain in original score denominators. |
| Quant | HumanEval task | Base status | Plus status |
|---|---|---|---|
| IQ2_XS | HumanEval/10 | fail | fail |
| IQ2_XS | HumanEval/32 | fail | fail |
| IQ2_XS | HumanEval/76 | pass | fail |
| IQ2_XS | HumanEval/91 | pass | fail |
| IQ2_XS | HumanEval/99 | pass | fail |
| IQ2_XS | HumanEval/132 | fail | fail |
| IQ2_XS | HumanEval/134 | pass | fail |
| IQ2_XS | HumanEval/141 | pass | fail |
| IQ2_XS | HumanEval/145 | fail | fail |
| IQ2_XS | HumanEval/151 | pass | fail |
| IQ2_XS | HumanEval/160 | fail | fail |
| IQ3_XXS | HumanEval/10 | fail | fail |
| IQ3_XXS | HumanEval/22 | pass | fail |
| IQ3_XXS | HumanEval/32 | fail | fail |
| IQ3_XXS | HumanEval/76 | pass | fail |
| IQ3_XXS | HumanEval/91 | pass | fail |
| IQ3_XXS | HumanEval/99 | pass | fail |
| IQ3_XXS | HumanEval/132 | fail | fail |
| IQ3_XXS | HumanEval/141 | pass | fail |
| IQ3_XXS | HumanEval/145 | fail | fail |
| IQ3_XXS | HumanEval/151 | pass | fail |
All missed practical rubric checks
| Quant | Task | Repeat | Score | Finish reason | Failed checks |
|---|---|---|---|---|---|
| IQ2_XS | research-vendor-filter | 0 | 90.91 | stop | $625 |
| IQ2_XS | agent-tool-sequence | 0 | 62.50 | stop | search query supplied; read URL is search placeholder; save includes title, body and source |
| IQ2_XS | executive-decision-memo | 0 | 85.71 | stop | $100 |
| IQ2_XS | executive-waiting-on | 0 | 88.89 | stop | approve |
| IQ2_XS | research-vendor-filter | 1 | 90.91 | stop | $625 |
| IQ2_XS | agent-tool-sequence | 1 | 62.50 | stop | search query supplied; read URL is search placeholder; save includes title, body and source |
| IQ2_XS | sysadmin-recovery | 1 | 80.00 | length | API response completed |
| IQ2_XS | executive-decision-memo | 1 | 85.71 | stop | $100 |
| IQ2_XS | executive-waiting-on | 1 | 88.89 | stop | approve |
| IQ2_XS | research-source-conflict | 2 | 90.00 | stop | superseded |
| IQ2_XS | research-vendor-filter | 2 | 90.91 | stop | $625 |
| IQ2_XS | agent-tool-sequence | 2 | 62.50 | stop | search query supplied; read URL is search placeholder; save includes title, body and source |
| IQ2_XS | sysadmin-recovery | 2 | 80.00 | length | no write/truncate file mode; API response completed |
| IQ2_XS | executive-decision-memo | 2 | 85.71 | stop | $100 |
| IQ2_XS | executive-waiting-on | 2 | 88.89 | stop | approve |
| IQ3_XXS | business-margin-forecast | 0 | 62.50 | stop | 1,680,000; 70%; 20% |
| IQ3_XXS | research-evidence-table | 0 | 90.00 | stop | forum |
| IQ3_XXS | agent-tool-sequence | 0 | 62.50 | stop | search query supplied; read URL is search placeholder; save includes title, body and source |
| IQ3_XXS | sysadmin-recovery | 0 | 80.00 | length | no write/truncate file mode; API response completed |
| IQ3_XXS | executive-decision-memo | 0 | 85.71 | stop | $100 |
| IQ3_XXS | executive-content-brief | 0 | 90.91 | stop | three evidence beats |
| IQ3_XXS | research-source-conflict | 1 | 90.00 | stop | superseded |
| IQ3_XXS | research-vendor-filter | 1 | 90.91 | stop | $625 |
| IQ3_XXS | sysadmin-python-bug | 1 | 66.67 | stop | complete average function with empty guard and ordinary calculation |
| IQ3_XXS | sysadmin-recovery | 1 | 80.00 | length | API response completed |
| IQ3_XXS | executive-decision-memo | 1 | 85.71 | stop | $100 |
| IQ3_XXS | executive-waiting-on | 1 | 88.89 | stop | approve |
| IQ3_XXS | agent-tool-sequence | 2 | 62.50 | stop | search query supplied; read URL is search placeholder; save includes title, body and source |
| IQ3_XXS | agent-parallel-plan | 2 | 90.00 | stop | parallel independent source branches |
| IQ3_XXS | sysadmin-recovery | 2 | 80.00 | length | no write/truncate file mode; API response completed |
| IQ3_XXS | executive-decision-memo | 2 | 85.71 | stop | $100 |
| IQ3_XXS | executive-waiting-on | 2 | 88.89 | stop | approve |
Dossier and long-context reliability
| Quant | Dossier actual prompt tokens | Valid completed responses | Full-marker recall responses | Empty finals | First dossier s | Warmed repeat median s | Maximum successful needle prompt tokens |
|---|---|---|---|---|---|---|---|
| IQ2_XS | 57135, 57135, 57135 | 3/3 | 3/3 | 0 | 52.16 | 21.81 | 124963 |
| IQ3_XXS | 57135, 57135, 57135 | 3/3 | 3/3 | 0 | 54.63 | 30.90 | 124963 |
Dossier output cap is 3,072 and reasoning budget 512. Repeat prompts may reuse prefixes; first-ingest and warmed-repeat times are separate. A nominal upstream 32K needle produced 32,804–32,805 actual prompt tokens, exceeding a 32,768 context plus output allowance. Those HTTP rejections are retained. Successful allocated contexts are not declared to pass their full capacity merely because shorter inputs worked.
| Quant | Needle run / allocation | Cases | Completed | Found | Errors | Empty finals | Actual prompt tokens |
|---|---|---|---|---|---|---|---|
| IQ2_XS | needles-128k-ctx131072 | 3 | 3 | 3 | 0 | 0 | 124962, 124962, 124963 |
| IQ2_XS | needles-16k-ctx32768 | 3 | 3 | 3 | 0 | 0 | 15146, 15146, 15147 |
| IQ2_XS | needles-32k-ctx32768 | 3 | 0 | 0 | 3 | 0 | None, None, None |
| IQ2_XS | needles-32k-ctx65536 | 3 | 3 | 3 | 0 | 0 | 32804, 32804, 32805 |
| IQ2_XS | needles-64k-ctx131072 | 3 | 3 | 3 | 0 | 0 | 64925, 64925, 64926 |
| IQ2_XS | needles-8k-ctx32768 | 3 | 3 | 3 | 0 | 0 | 6920, 6920, 6921 |
| IQ3_XXS | needles-128k-ctx131072 | 3 | 3 | 3 | 0 | 0 | 124962, 124962, 124963 |
| IQ3_XXS | needles-16k-ctx32768 | 3 | 3 | 3 | 0 | 0 | 15146, 15146, 15147 |
| IQ3_XXS | needles-32k-ctx32768 | 3 | 0 | 0 | 3 | 0 | None, None, None |
| IQ3_XXS | needles-32k-ctx65536 | 3 | 3 | 3 | 0 | 0 | 32804, 32804, 32805 |
| IQ3_XXS | needles-64k-ctx131072 | 3 | 3 | 3 | 0 | 0 | 64925, 64925, 64926 |
| IQ3_XXS | needles-8k-ctx32768 | 3 | 3 | 3 | 0 | 0 | 6920, 6920, 6921 |
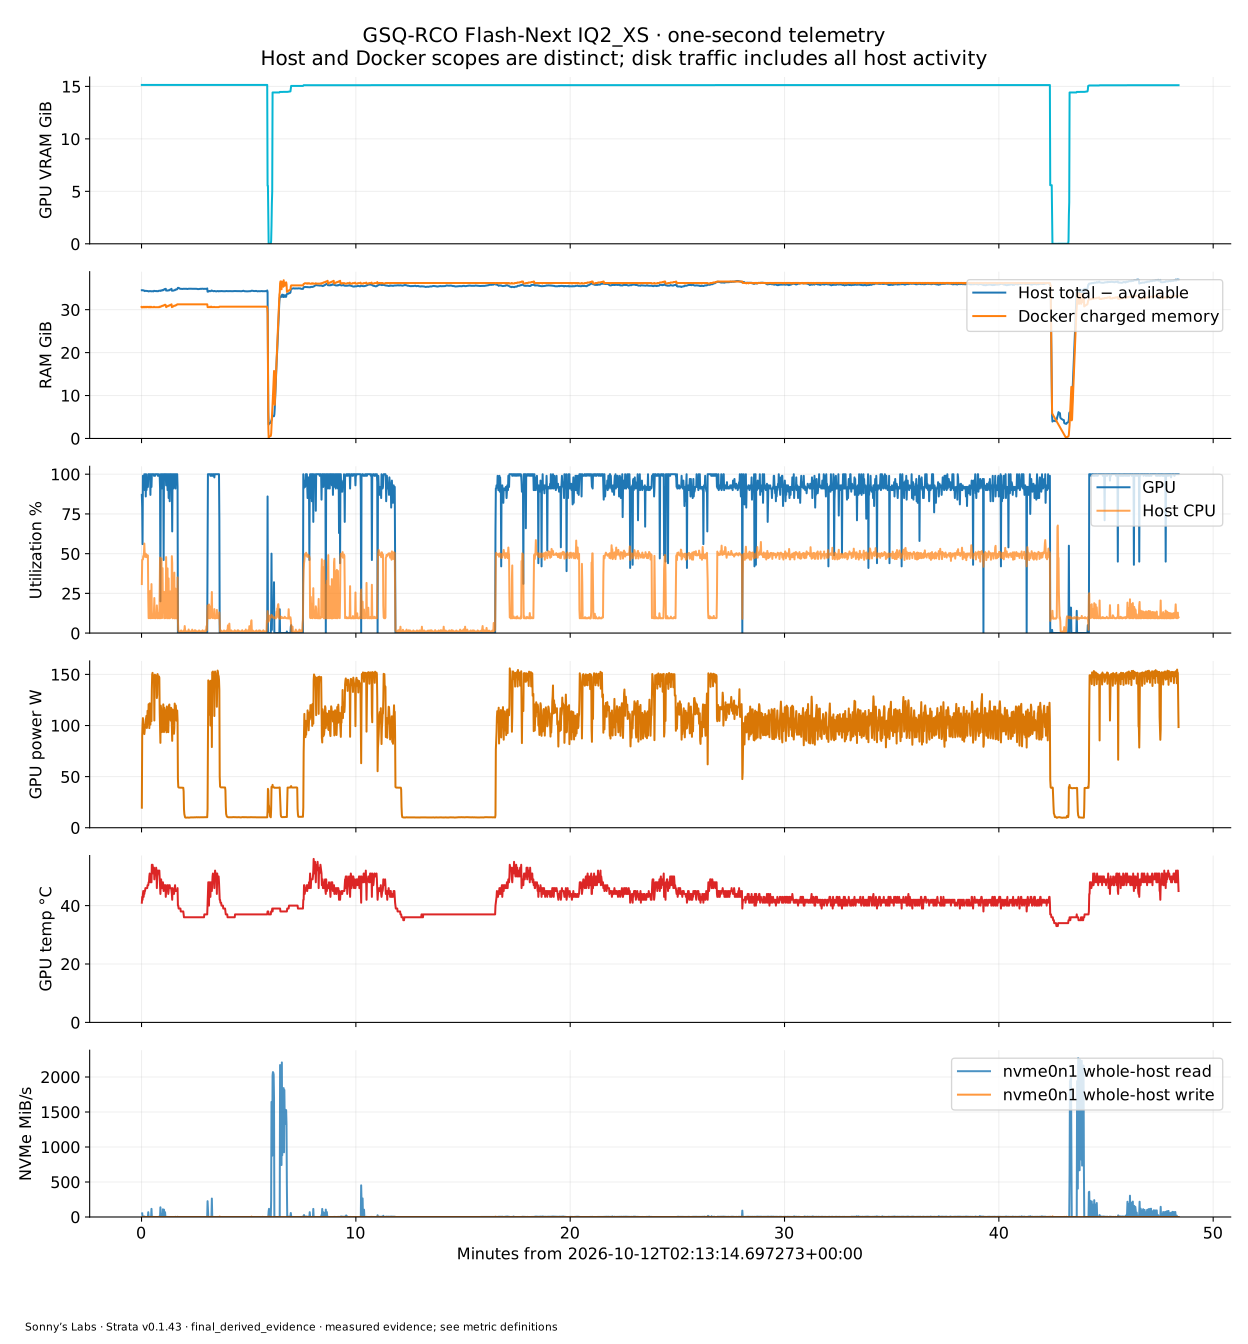
Memory, VRAM, power and SSD activity
| Quant | Standard-suite observed VRAM peak GiB | Container charged-memory peak GiB |
|---|---|---|
| IQ2_XS | 15.14 | 31.25 |
| IQ3_XXS | 15.16 | 42.07 |
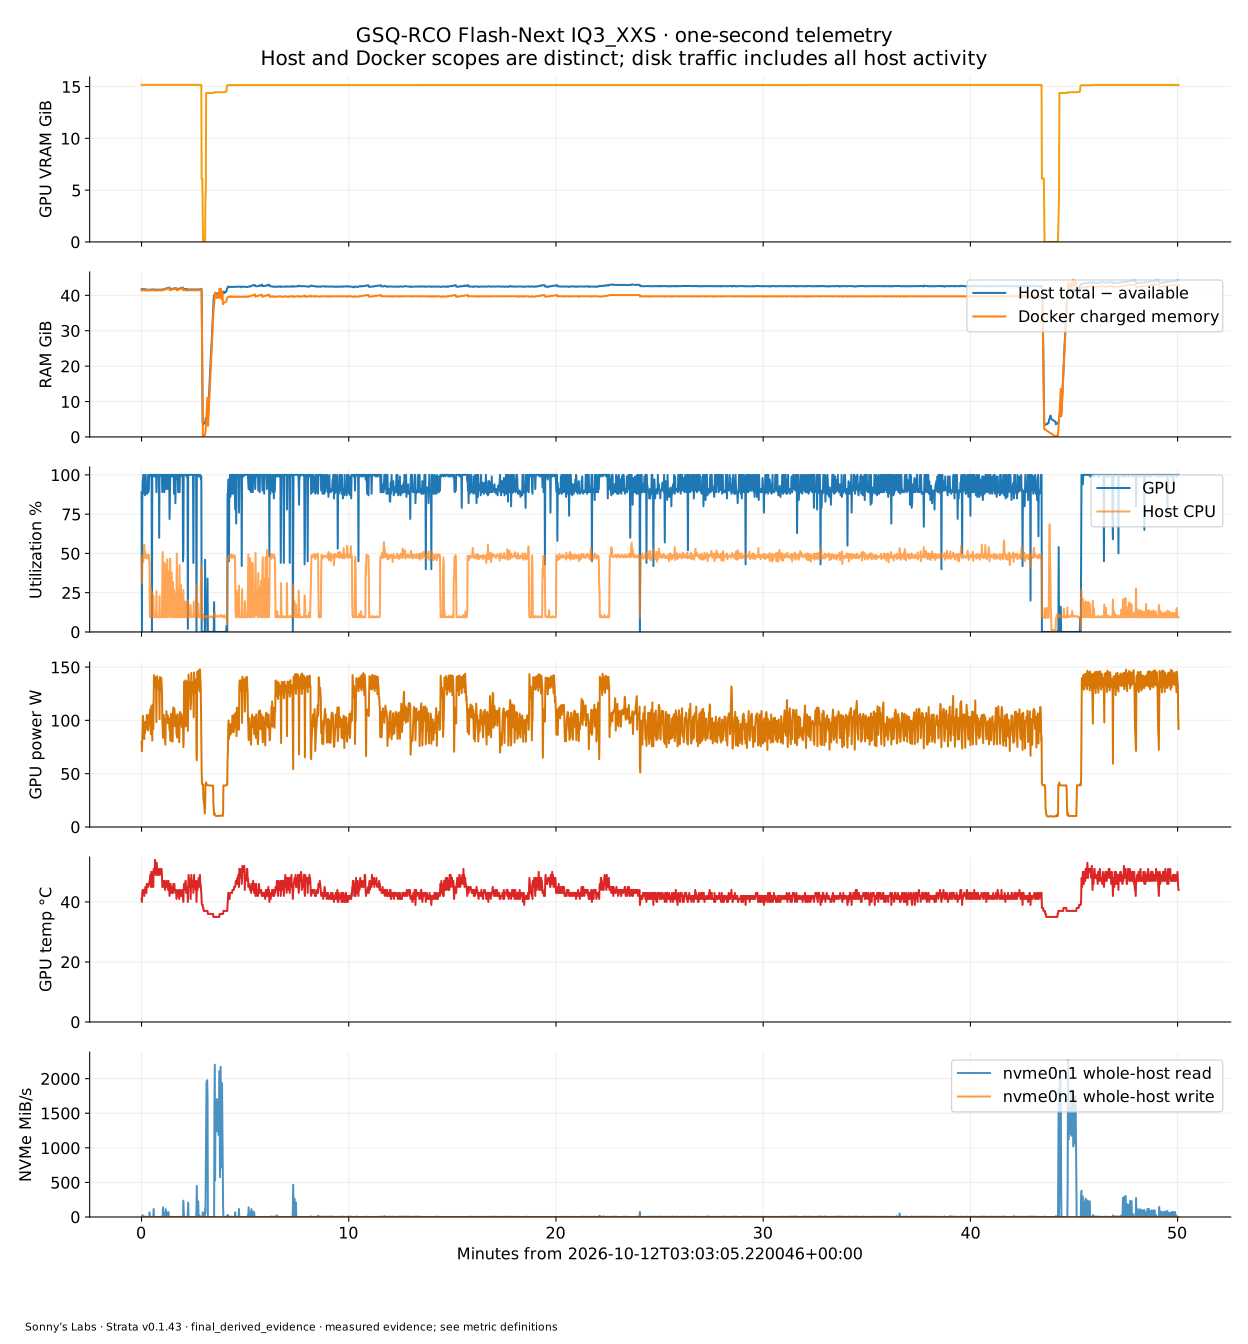
One-second UTC-aligned host, LXC, process and Docker cgroup records are preserved separately. Host physical-NVMe reads include all activity; they are not labeled model-specific. Per-process I/O and container block I/O have narrower attribution. Cgroup memory includes charged cache and shared memory; host available RAM and swap activity are separate fields in the structured evidence. Linux Cached includes Shmem/tmpfs, including shared expert allocations, so it must not all be described as evictable filesystem cache. Raw Cached, Shmem, Cached-minus-Shmem, Mlocked and Unevictable, plus overlapping cgroup file/shmem counters, are preserved separately.
| Entire host capture UTC | Samples | RAM total−available peak GiB | Available minimum GiB | VRAM observed peak MiB | GPU power peak W | GPU temperature peak °C |
|---|---|---|---|---|---|---|
| 2026-10-12T01:58:40.697161+00:00 to 2026-10-12T03:53:55.822063+00:00 | 6915 | 44.21 | 14.55 | 15,528 | 155.9 | 56 |
This entire-capture summary includes model loading, gaps and isolated scoring during the captured experiment period. It is not a per-model attribution. Per-phase windows below exclude unrelated stages.
Host RAM, swap and whole-NVMe traffic by completed phase
| Quant | Phase | RAM total−available peak GiB | Available minimum GiB | Swap used peak MiB | Swap-in pages | Swap-out pages | NVMe reads GiB | Max NVMe read MiB/s | NVMe writes MiB |
|---|---|---|---|---|---|---|---|---|---|
| IQ2_XS | practical | 36.20 | 22.56 | 54.94 | 55 | 0 | 0.916 | 7.90 | 66.08 |
| IQ2_XS | dossier | 36.69 | 22.06 | 54.94 | 3 | 0 | 0.209 | 16.38 | 8.94 |
| IQ2_XS | humaneval | 36.47 | 22.28 | 54.94 | 19 | 0 | 2.260 | 91.38 | 75.58 |
| IQ2_XS | official-optional-65536 | 36.05 | 22.70 | 55.74 | 14 | 0 | 0.913 | 115.84 | 19.74 |
| IQ2_XS | official-standard-32768 | 34.86 | 23.89 | 63.19 | 207 | 0 | 0.813 | 138.46 | 15.30 |
| IQ2_XS | needles-128k-ctx131072 | 37.01 | 21.74 | 54.77 | 2 | 0 | 4.474 | 304.22 | 12.48 |
| IQ2_XS | needles-16k-ctx32768 | 34.47 | 24.29 | 62.79 | 57 | 0 | 0.276 | 263.72 | 7.75 |
| IQ2_XS | needles-32k-ctx32768 | 34.32 | 24.43 | 62.79 | 0 | 0 | 0.000 | Pending / unavailable | 0.00 |
| IQ2_XS | needles-32k-ctx65536 | 35.87 | 22.88 | 55.61 | 4 | 0 | 1.097 | 452.30 | 4.88 |
| IQ2_XS | needles-64k-ctx131072 | 36.57 | 22.18 | 54.77 | 2 | 0 | 2.235 | 360.44 | 6.58 |
| IQ2_XS | needles-8k-ctx32768 | 34.35 | 24.40 | 62.79 | 0 | 0 | 0.093 | 92.39 | 0.47 |
| IQ3_XXS | practical | 42.90 | 15.86 | 54.60 | 5 | 0 | 1.062 | 9.92 | 87.82 |
| IQ3_XXS | dossier | 43.07 | 15.68 | 54.59 | 3 | 0 | 0.196 | 17.28 | 9.71 |
| IQ3_XXS | humaneval | 42.94 | 15.81 | 54.59 | 17 | 0 | 2.479 | 73.94 | 98.95 |
| IQ3_XXS | official-optional-65536 | 43.03 | 15.73 | 54.70 | 2 | 0 | 0.909 | 139.05 | 20.59 |
| IQ3_XXS | official-standard-32768 | 42.23 | 16.52 | 54.70 | 3 | 0 | 0.799 | 138.08 | 15.43 |
| IQ3_XXS | needles-128k-ctx131072 | 44.21 | 14.55 | 54.44 | 2 | 0 | 4.473 | 304.97 | 18.12 |
| IQ3_XXS | needles-16k-ctx32768 | 41.72 | 17.04 | 54.70 | 8 | 0 | 0.276 | 208.43 | 7.07 |
| IQ3_XXS | needles-32k-ctx65536 | 42.75 | 16.00 | 54.60 | 4 | 0 | 1.099 | 467.58 | 9.19 |
| IQ3_XXS | needles-64k-ctx131072 | 43.80 | 14.95 | 54.44 | 0 | 0 | 2.237 | 379.57 | 13.36 |
| IQ3_XXS | needles-8k-ctx32768 | 42.21 | 16.54 | 54.70 | 5 | 0 | 0.313 | 236.42 | 6.54 |
Swap activity uses kernel page counters (4 KiB pages on this machine), distinct from swap allocation. Host total-minus-available is an available-memory pressure measure; it is not process RSS. LXC procfs is virtualized and can expose cache counters with different accounting. Docker memory.events and stopped-container OOM flags are retained independently. Measurements during a phase use its first and last one-second samples; boundary traffic and subsecond peaks can be missed.
| Quant | Context | GPU expert slots | GPU expert cache GiB | Expert arena GiB | Resident KV tokens | MTP maximum | Aggregate speculation | Lookup field | Free VRAM MiB |
|---|---|---|---|---|---|---|---|---|---|
| IQ2_XS | 32768 | 7073 | 9.47 | 27.32 | 0 | 4 | 6 | 3 | 527 |
| IQ2_XS | 65536 | 7031 | 9.42 | 27.44 | 32768 | 4 | 6 | 3 | 529 |
| IQ3_XXS | 32768 | 5518 | 8.94 | 34.39 | 0 | 4 | 6 | 3 | 505 |
| IQ3_XXS | 65536 | 5480 | 8.88 | 34.51 | 32768 | 4 | 6 | 3 | 505 |
Requested cache/prefill are auto, LOW_RAM resident on, KV int8, requested MTP spec 4 / minimum probability 0.5, VRAM reserve request 1,024 MiB. Actual free VRAM is the engine-reported resolved value; the reserve request is not a promise of 1 GiB remaining after all allocations. The aggregate speculation field includes lookup behavior and must not be mislabeled as six MTP tokens. Vision, MCP execution and batching are off.
Precompiled Docker and security
The engine was compiled for SM120 using CUDA 13.0.0 from the exact Strata and llama.cpp revisions before runtime. Verified model files and packs live outside the image. The serving entry point checks the engine digest and directly starts the API; it refuses MCP/vision configuration. Inference uses network none, nonroot UID 65534, read-only root/models, zero capabilities, no-new-privileges, and no Docker socket or management mounts. GPU access still shares the host kernel and NVIDIA driver.
Both quantizations passed real offline health and inference tests independently. The initial Syft/Grype assessment reported 550 package matches, including 14 high matches across three vulnerability IDs. A separately tagged runtime updated OS/CUDA packages without changing the engine hash: 281 matches, 253 medium, 26 low, two negligible, zero high/critical. These scans cover the retained inference images; they do not scan the host, NVIDIA driver, scorer or workstation. These are scanner matches, not independently demonstrated exploits or a safety certification. The retained image archive permits exact deployment; byte-identical rebuilding is not guaranteed because apt repositories were live.
Official startup can invoke setup and downloads; this deployment separates preparation from serving. Bob’s retained source captions identify concerns about permissions, executable downloads and agent-driven installation. The measured mitigations address those operational paths, while remaining trust in native parsers, CUDA/driver binaries, dependencies and the host kernel is disclosed. No maliciousness or endorsement is claimed.
What the memory hierarchy actually does
The pinned implementation puts attention/shared weights, MTP and a hot-expert cache on the GPU. In the tested LOW_RAM resident variant, RAM holds the expert-cache complement, not a redundant copy of every GPU-resident expert; CPU expert computation and PCIe GPU work cooperate. IQ2 at 64K resolved 7,031 GPU cache slots (9.42 GiB) and a 27.44 GiB page-locked expert complement. Some prompt-path borrowed slots retain RAM copies. A 32,768-token resident KV window uses VRAM while other KV state lives in pinned RAM.
The separate 28.8 GB PLE n-gram shard remains an SSD workload: the engine’s default direct I/O reads selected rows past the OS page cache. The observed log confirms a direct-read probe and PLE enabled. Zero expert-file blob reads during resident decoding therefore does not mean zero SSD reads. Initial loading and later PLE traffic must be distinguished. Pinned upstream architecture.
Developer claims and measured scope
The pinned README reports IQ2_XS at 79 decode tokens/s and 2,090 prefill tokens/s on a 32K prompt, and IQ3_XXS at 62 and 1,750, on an RTX 5070 12GB/Ryzen 5 7600 using engine 0.1.26 for those rows. Our IQ2 official standard chat median is 81.9 decode tokens/s, and the optional 32K-input prefill median is 2,183.4. These are broadly similar scales, an engineering observation rather than a controlled replication: GPU, CPU, instruction set, PCIe, engine version and output length differ. The same-model quantization comparison in this experiment is the controlled comparison. Model-card AIME/GPQA/LiveCodeBench claims are different evaluations and cannot be confirmed by these Sonny’s Labs tasks alone. Pinned developer speed table.
Provenance and reproducibility
{
  "name": "Strata",
  "version": "0.1.43",
  "commit": "7695859aa13afb248bdb4d36f9b2e95707db079d",
  "llama_cpp_commit": "3cf03257f219afbe7334045ff7c6a06ac68c627d",
  "image": "sha256:f759e6167315dac77292d394a470240493dad78de6d23dd270eaa5c7ffc3e143",
  "driver": "615.71.09",
  "cuda_build": "13.0.0",
  "architecture": "sm_120"
}
Quantization repository revision: ed59f92082b1e93c0e96d60a8b11aab089b52f09. Every GGUF and MTP safetensor was checked against its pinned hash. The PLE shard is shared only after complete hash agreement; native experts and pack index v3 are prepared separately for each quantization. The underlying architecture is described by its creators as a 125B MoE with 6B active parameters plus a 51B n-gram table and 4B MTP component; these are creator claims, not measured active memory requirements. Pinned model card.
Local reproduction tooling and exact commands are retained with the experiment. Apt resolution was from signed live repositories rather than a frozen snapshot; preserve the image archive and wheel/source receipts for strongest repeatability. Build-time networking was allowed. Runtime offline inference was tested separately.
Historical continuity and limitations
report4.firetussin.com is the user-confirmed latest historical report. The verified local 17-configuration source is the comparison baseline; the live endpoint returned HTTP 403 during this experiment. Original datasets, v2.1 scoring functions and category weights are retained. The older generator hardcodes 17 Qwen3.8-27B queue entries and cannot represent this two-model Strata/upstream-suite experiment unchanged, so this wrapper reuses its scoring output, font assets and data/handoff contract.
A fast empty answer is still a failed answer. The original practical/coding index does not measure long-context quality. All 102 report4 fixed/adaptive responses were rechecked against raw artifacts. HauhauCS Q2_K_P retains its 97.61 index and 6.90 s measured adaptive median, but has 0/6 valid final answers and zero validated dossier quality. It is excluded from successful-speed and reliability-qualified recommendations. Thirteen of the 17 historical configurations completed all six responses with all 14 literal markers; this stricter gate is a separately labeled evaluation, not a change to the original index.
Recalculated report4 results — different model and runtime
| Historical Qwen3.8-27B configuration | Original practical/coding /100 | HumanEval+ % | All-request adaptive median s | Valid completed finals | Full-marker recall finals | Empty finals | Adaptive successful-speed eligible |
|---|---|---|---|---|---|---|---|
| Qwen3.8-27B GSQ-RCO IQ3_S MTP | 97.70 | 90.24 | 31.51 | 6/6 | 6/6 | 0 | True |
| Qwen3.8-27B HauhauCS Uncensored Q2_K_P MTP | 97.61 | 85.98 | 6.90 | 0/6 | 0/6 | 6 | False |
| Qwen3.8-27B Pi IQ2_M control | 97.58 | 82.93 | 39.53 | 6/6 | 6/6 | 0 | True |
| Qwen3.8-27B Pi RCO allocation-transfer IQ3_XXS | 97.58 | 87.20 | 47.07 | 6/6 | 6/6 | 0 | True |
| Qwen3.8-27B GSQ-RCO IQ3_XXS MTP | 97.37 | 87.20 | 30.52 | 6/6 | 6/6 | 0 | True |
| Qwen3.8-27B GSQ-RCO IQ3_XXS | 97.31 | 86.59 | 55.26 | 6/6 | 6/6 | 0 | True |
| Qwen3.8-27B Unsloth UD-Q2_K_XL | 97.09 | 85.37 | 42.32 | 6/6 | 6/6 | 0 | True |
| Qwen3.8-27B orcarouter Uncensored IQ3_XXS MTP | 97.00 | 87.20 | 26.28 | 6/6 | 6/6 | 0 | True |
| Qwen3.8-27B HauhauCS Uncensored IQ3_XS MTP | 96.77 | 86.59 | 28.07 | 6/6 | 6/6 | 0 | True |
| Swift-Qwen3.8-27B IQ2_S | 96.52 | 78.66 | 35.89 | 6/6 | 6/6 | 0 | True |
| Qwen3.8-27B GSQ-RCO IQ3_S | 96.44 | 88.41 | 53.75 | 6/6 | 0/6 | 0 | True |
| Qwen3.8-27B GSQ-RCO IQ2_S MTP | 96.43 | 85.37 | 26.93 | 6/6 | 3/6 | 0 | True |
| Qwen3.8-27B GSQ-RCO IQ2_S | 95.54 | 85.37 | 35.96 | 6/6 | 6/6 | 0 | True |
| Qwen3.8-27B HauhauCS Uncensored IQ2_M MTP | 95.26 | 89.02 | 25.19 | 6/6 | 3/6 | 0 | True |
| Qwen3.8-27B GSQ-RCO IQ2_XS MTP | 95.00 | 87.20 | 23.07 | 6/6 | 6/6 | 0 | True |
| Qwen3.8-27B Unsloth UD-IQ2_S | 94.92 | 73.17 | 48.49 | 6/6 | 6/6 | 0 | True |
| Qwen3.8-27B GSQ-RCO IQ2_XS | 93.46 | 85.98 | 43.35 | 6/6 | 6/6 | 0 | True |
Full recalculated report4 reference · Recalculated raw-source audit and rankings. The original report4 publication and saved scores are preserved. Strict recall qualification requires completed nonempty stop responses and 14/14 original literal markers; this heuristic does not establish semantic accuracy. Historical adaptive latency and Strata fixed cached repeats differ in runtime/configuration; ranks are not pooled.
- IQ2_XS vs IQ3_XXS is a same-model, same-hardware comparison. Historical report4 uses Qwen3.8-27B and a different runtime; cross-model differences cannot be attributed solely to quantization.
- Both quantizations use mixed tensor formats and share the verified PLE shard; the labels do not mean every tensor uses two or three bits.
- Model preparation warmed filesystem cache. No storage-cold performance is claimed. Model load, initial uncached prompt processing and prefix-cached follow-ups are separate measurements.
- Dossier repeats retain the existing benchmark prompts and cache policy. First response and warmed repeats are reported separately; cached prefill rates must not be used as full-input throughput.
- The original v2.1 practical rubric and weighted score are retained. Hermes literal-marker heuristic is reported separately, with empty finals explicitly zeroed; it is not an independent broad-quality assessment.
- The practical rubric checks explicit content and structure, not arbitrary semantic correctness. These fixed synthetic workload scores are not a general intelligence or production-agent guarantee.
- The practical/coding index excludes long-context quality. Empty final answers count as dossier failures and receive zero validated dossier quality, even if reasoning exists or the API reports stop. Successful-speed rankings require valid completed answers. A separate full-marker reliability gate does not alter the original weighted index.
- HumanEval+ uses one generation per problem (pass@1); practical tasks have three repeats. Small score differences have not been established as statistically significant or universal quantization effects.
- Strict JSON-schema enforcement is unavailable in the tested image because an optional dependency is absent. Successful JSON examples and forced client tool calls do not prove general schema/tool reliability.
- Server-side MCP execution and vision are disabled. The optional two-client speed test uses one serial service slot, not GPU batching.
- Nonstreaming original Sonny clients measure end-to-end latency and retain engine timings; client TTFT is measured by the upstream streaming suite, not inferred for every Sonny request.
- One-second telemetry can miss subsecond peaks. Host physical-device disk traffic is not model-specific. Docker charged-memory, process RSS, page cache and host memory have distinct definitions.
- The engine retains upstream route-tail-skip default 7. Missing experts may be skipped, so speed/quality results include that approximation. Greedy output can vary with draft grouping, adaptive expert placement and prefix-cache state; fixed seed/temperature do not promise byte-identical responses.
- Apt repositories and some rebuilt scorer transitive dependencies are not snapshot-pinned. Source/image/model hashes and package inventories improve auditability but do not constitute a security certification.
Cost and attribution
Local owned hardware. No cloud rentals or purchases; electricity, amortization, bandwidth and historic quant creation not metered. Zero rental is not zero total project cost.
Credit Strata maintainers and contributors, Qwen model creators, ISTA-DASLab/GSQ-RCO quantization contributors, llama.cpp/ggml, NVIDIA and container-tooling projects, EvalPlus, and Unbiased Bob’s independent security work. No endorsement is implied. The original model and quantization cards carry separate license metadata; do not infer a blanket license from one card.
Structured evidence · Verification
- Pinned Strata source
- Community benchmark methodology
- Quantized model revision
- Original Qwen model
- Unbiased Bob’s independent security discussion
- Bob’s reference fork (not tested engine)
Retained reproducibility and security documents: Exact reproduction commands · Artifact manifest · Supply-chain review · Bob comparison and caption provenance.